The lead, the desk, and the judges
In this note
Hand a single AI agent a big, messy creative project and it acts like an overeager solo founder pulling an all-nighter.
For the first three hours it's on fire. By hour six it's forgetting rules you agreed on at lunch, and by morning it's quietly grading its own shortcuts an A-minus just to cross the finish line. If you spin up ten agents with no org chart, you get something funnier and worse: ten solo founders editing the same files, inventing clashing styles, and congratulating each other on broken builds.
I hit that exact wall early on while building Home Port from my phone. Our Linux container had restarted three times in seven hours under Blender memory spikes, my main session's context was getting sluggish, and finished 3D props were sitting in a single-file line waiting to be merged and rendered.
So I asked: "can we start to have you orchestrating other sessions to conserve your memory? and also to help parallelize?" Within minutes we had an integration desk and parallel builders running around the clock. Everything started clicking once we organized the sessions the exact way you'd organize a small, sharp human team.
Keeping noise out of the lead's head
Multi-agent setups usually fall apart the moment two threads share fuzzy responsibility for the same files. We split the work into three clean roles:
- The Lead (my single point of contact): Only the lead talked to me, logged my exact words, and wrote down a tie-breaker ruling whenever my notes left wiggle room. It never burned context wrestling git conflicts or scrolling through thousand-line test outputs.
- The Desk (integration and triage): Every builder reported to the desk, never straight to me. Before claiming anything worked, a builder had to merge the desk's branch, run the checks, and push to its own isolated branch. The desk merged clean slices, visually inspected every new render, and sent the lead a tight digest capped at twelve lines across six buckets: merged, held, ruled, for him, needs you, next.
- Scoped Builders (one owner per slice): One builder owned the wall TV, another owned the harbor and sky outside the window, another owned the Mac render runner, and others owned the book covers, materials and plants, props, kitchen, and static web page. Nobody stepped on anyone else's files.
That twelve-line digest between the desk and the lead did most of the heavy lifting. Coding agents produce a ton of noisy trial-and-error chatter while figuring things out. Trapping all that noise inside disposable builder windows meant my lead session stayed clear-headed for days.
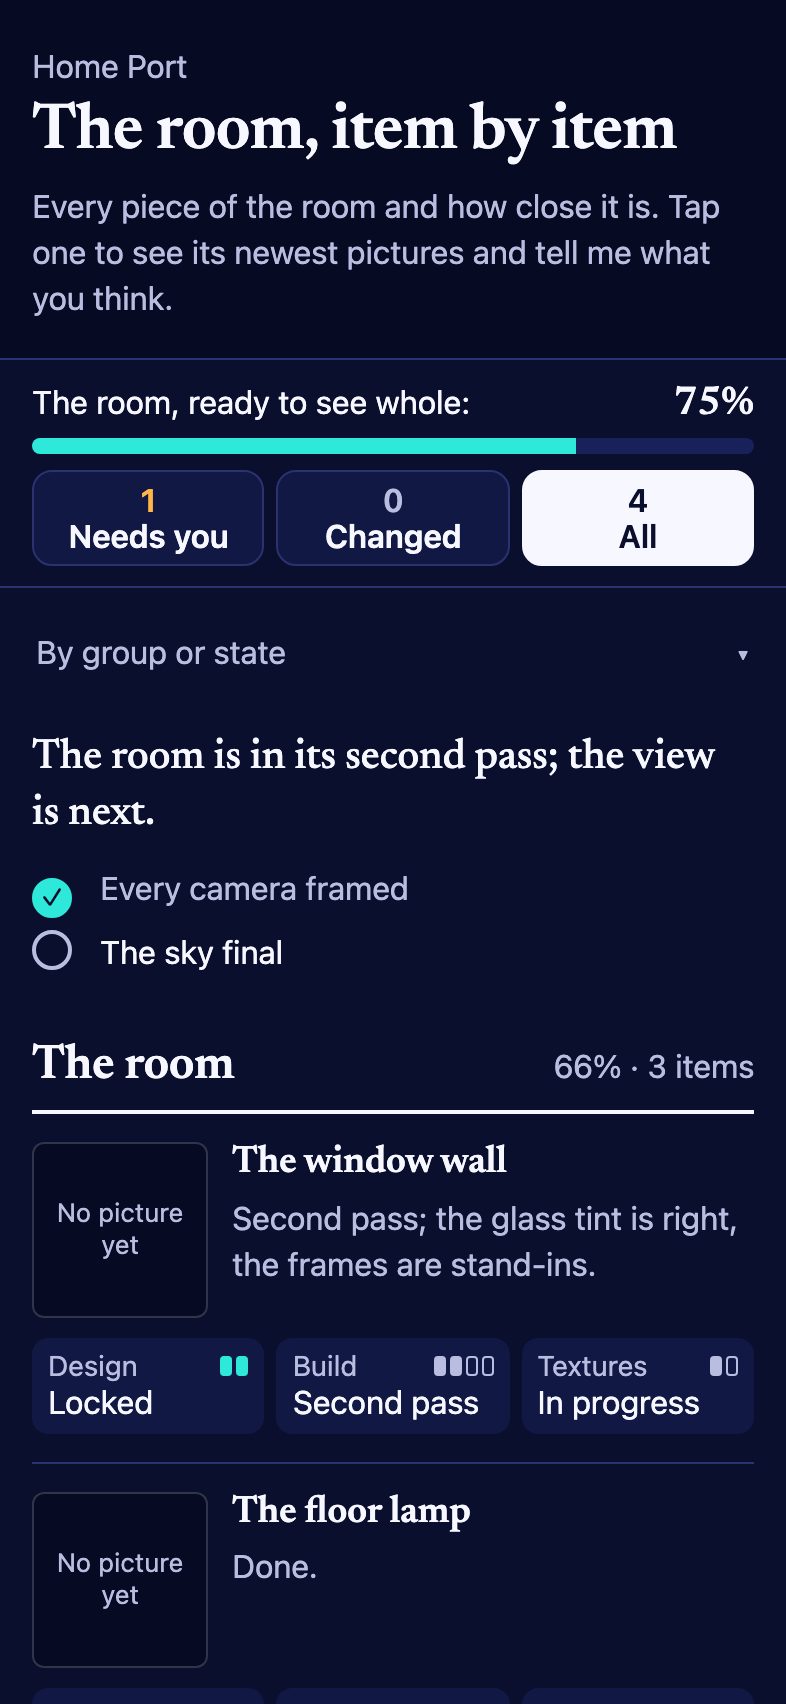
The desk also kept one live work board where every row had to spell out what "done" meant in plain, testable facts rather than vibes:
| What | Who | Done when |
|---|---|---|
| The posts at /posts/\ |
a new posts session | merged, the walk's post checks green, frames looked at |
| The Resume view restyled to the new frames | the TV builder | merged, site tests green, frames looked at |
| My benchmark turned into a night-by-night render estimate | render worker 3 | the lead names the commit for the Mac |
"Looks good" isn't a finish line an agent can verify; "merged, site tests green, frames looked at" is. Even overnight Mac render batches went through the desk's automated byte-budget and visual checks the moment they uploaded, catching telescope stills that had been exported at quality 88 and blew past their byte budgets.
Builders never grade their own homework
Asking the same session that just spent twenty minutes modeling an espresso machine "Does this look good?" is a waste of tokens. Like most of us, it squints generously at its own work and moves on.
So we separated Builders from Judges and Breakers. Builders wrote code and geometry, and never graded their own output. Judges critiqued rendered frames, and were forbidden from editing files.
Our judge bench included a creative director, an art director, a technical director, a privacy reviewer, an interior stylist, and my personal favorite: a grumpy senior hiring executive who only looks at phone screenshots and couldn't care less how clever your Python script is if your headline takes ten seconds to read. Alongside them sat a QA breaker whose whole job was trying to break links, clip text, or trip fallbacks before a preview ever reached my phone.
Two small habits gave those reviews real teeth. Every review had to list the exact image files it actually opened, and two judges scored each frame blind before seeing each other's notes. On their first pass over our hero room props, scores landed between 4.5 and 6.5 out of ten, which bruised some silicon egos and immediately raised the bar on the room.
Even then, funny bugs slipped past until we turned them into hard checks. At one point, one of our dogs (Obi) had a tiny bright catch-light meant to reflect only in his dark eyes. The scene loader dropped that light-linking rule, turning poor Obi's eyeball highlight into a floodlight that blew out the entire living room across a whole batch of renders. Instead of adding another polite reminder to a markdown file, that bug became a git check verifying the fix commit was present before any new room frame could be sent for review.
Calling time on infinite agent nitpicks
Left unsupervised, conscientious critic-and-fixer loops develop a hilarious failure mode: they will polish invisible baseboards until your weekly usage quota evaporates.
Late one night I caught sub-agents spinning up fresh rounds over tiny micro-details nobody on a phone or monitor would ever see. The lead even mentioned it was holding an unrequested touch-up pass on our dog Chewy's eyes.
I stepped in right away: "leave Chewy, he was fine" and "let's try and start getting closer to done instead of infinite nits that didn't come from me".
That became house law. Agents only fix things on their own if a normal visitor would read them as broken: clipped copy, dead buttons, missing assets, or clear visual bugs. Everything else waits for my eye. Sure enough, the very next day another unrequested polish loop tried to sprout anyway, and I had to lay it down a second time: "I'm the one that decides nit's so if it's very minor details let me raise them and let's not infinitely spin sub agents."
Sometimes steering meant killing a side quest mid-flight. When a job was about to try cooler lamps while our living-room rug still looked faded and washed out, I sent one all-caps text: "DONT WASTE YOUR TIME ON COOLER LAMPS, CANCEL THAT JOB - MAKE THE RUG THE DARKER BLUE YOU JUST SHOWED AND MOVE ON". The rug got its darker blue, and we gained a standing rule: push the pigment, never touch the light.
Running the same playbook on other builds
Once you separate planning, building, and reviewing into distinct seats, you end up using the same setup everywhere:
- Plan on Opus, execute on Sonnet (CrashCalc): Deep domain audits and architecture run on Claude Opus, which writes a tight, step-by-step spec naming exact files, failing tests to write first, and boundaries not to touch. Claude Sonnet executes each slice inside its own Git worktree and stops to flag mismatches instead of improvising.
- Swapping the lead across quota walls: When Claude hit a weekly usage cap during a big CrashCalc push, Codex stepped straight into the lead seat using the repo's written state files, and Claude re-reviewed those landings once its window reset.
- Moving forward on recommended leans (Messina OS): Whenever parallel TV-launcher threads hit a product trade-off while I'm away from my phone, they post a short question with a bolded recommended default and keep building on that lean until I say otherwise.
Which model sits in which chair matters a whole lot less than keeping the chairs separate. Agents are incredible at parallel throughput, and terrible at knowing when to stop polishing the baseboards. Setting the bar, keeping builders and critics honest, and calling "good enough, ship it" is still very much the human job.